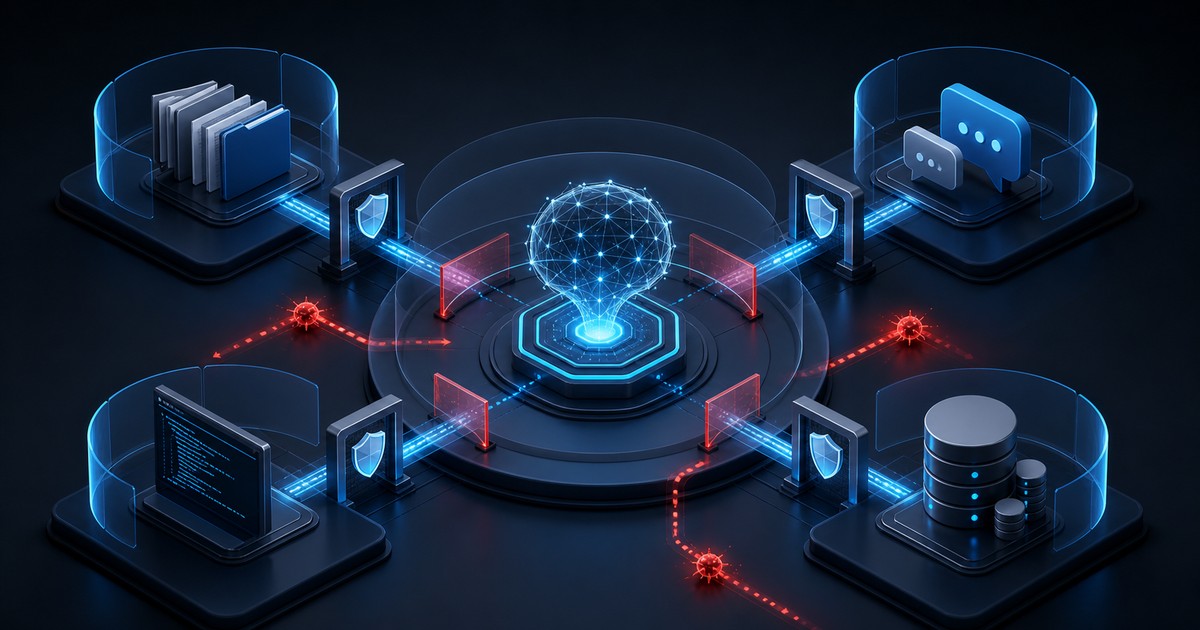
Threat modeling an AI agent with tool access starts with a simple question: what can this system cause, not merely what can it say? A useful model follows every path from an instruction to a tool call, a sensitive asset, and a business consequence. It then limits authority, records evidence, and defines a safe stop. This turns a vague concern about AI risk into a reviewable map of identities, permissions, data flows, and failure modes.
Model capabilities before prompts
Begin with the agent identity and enumerate each tool it can invoke. Include search, file access, messaging, code execution, customer records, payment systems, and administrative consoles if they are reachable. For every connection, name the credential, the owner, the allowed operation, and the data returned. A prompt is only one control surface. The more important boundary is whether the runtime can read, write, send, delete, or approve.
Assets deserve the same precision. Separate public reference material from internal documents, personal data, secrets, and regulated records. A medical data security case is useful here because it shows why the data path and operating controls matter more than a generic assurance. Treat the page as an example of boundary-focused delivery, not as proof that another system is safe.
Now draw trust boundaries between the user, model, orchestration layer, tool adapter, external service, and human reviewer. Ask where untrusted text can enter. A document, support ticket, webpage, or tool response may contain instructions that compete with the approved task. The model should not gain more authority merely because hostile content looks confident.
Turn abuse paths into control decisions
Write abuse cases as concrete sequences. An attacker places a hidden instruction in a document; the agent reads it; the tool adapter accepts a destructive request; the system acts under a broad credential. Another path may start with an honest user who asks for a summary but receives data from the wrong tenant. A third may involve a correct tool call that runs twice after a timeout.
Each path should end in an enforceable control. Use narrow credentials, explicit allowlists, tenant checks, confirmation for irreversible actions, output filtering, and limits on volume or scope. A human review step is valuable only when the reviewer can see the proposed action, source evidence, and affected object. Blind approval adds delay without changing risk.
Verification should be separate from generation. The release notes for precision-focused tool routing illustrate the value of explicit completion checks and bounded interfaces. The transferable lesson is procedural: an agent should return a receipt that another process can inspect, rather than declaring success from its own narrative.
Test the boundaries with realistic failures
A threat model becomes useful when the team can challenge it. Test revoked credentials, malformed tool output, conflicting instructions, cross-tenant identifiers, duplicate requests, partial outages, and a reviewer who rejects the action. Confirm that the system fails closed where the consequence is material and degrades safely where continuity matters.
Stage the tests in the same order as the risk grows. The staged BCI playbook concerns market execution, yet its sequencing principle applies cleanly: prove a narrow boundary before exposing a wider one. Start in a disposable environment, then use read-only production data, and only later consider constrained writes with rollback.
Keep the model current. Tool definitions change, vendors add features, credentials accumulate permissions, and people invent new shortcuts. Review the threat map when any capability, data source, identity, or approval path changes. The result should be a living control document with named owners, test evidence, residual risks, and an explicit decision about what the agent must never do.
Frequently Asked Questions
Include identities, tools, credentials, assets, trust boundaries, untrusted inputs, possible actions, abuse paths, approval points, evidence records, recovery options, and residual risks.
No. Excessive permissions, tenant mix-ups, duplicate actions, insecure tool adapters, secret exposure, weak review, and misleading success reports can be equally consequential.
Require approval when the action is difficult to reverse or materially affects money, access, people, external communications, customer data, or production systems.
Review it whenever tools, models, credentials, data sources, workflows, vendors, or approval rules change, and after tests reveal an unmodeled failure path.
If your agent already touches business systems, an AI governance and agent audit can map its real authority, evidence gaps, and highest-consequence paths before broader access is granted.