The hardware budget for running AI locally should be built from a tested workload, not from a shopping list. The visible accelerator may dominate attention, but memory fit, storage, system memory, networking, power, cooling, resilience, and operator time determine whether the machine can serve real work. A quote without those layers is an incomplete planning input.
Begin with a capacity envelope. Define the candidate model artifact, context pattern, expected concurrent use, acceptable response time, operating hours, and growth assumption. Mark every number as observed, vendor-stated, or estimated. This prevents a convenient estimate from quietly becoming a promise.
Measure the workload before specifying parts
Run the intended model and serving stack on representative inputs wherever possible. Record accelerator memory, system memory, storage footprint, load time, response-time distribution, throughput, and power draw. Include long contexts, peak concurrency, and restart behavior. A short single-user prompt rarely exposes the condition that sets the budget.
If direct testing is not yet possible, create a provisional range from official model and deployment documentation. Keep contingency visible and require a benchmark before procurement approval. The review of power, cooling, and land constraints shows why compute capacity cannot be separated from its environment, though the scale of your installation must be measured independently.
Decide whether the first system is a workstation, a shared server, or rented dedicated capacity. Each choice changes access control, maintenance windows, noise, heat, network design, and recovery. Include the physical location and the person who can safely restore service after a failure.
Budget the complete serving system
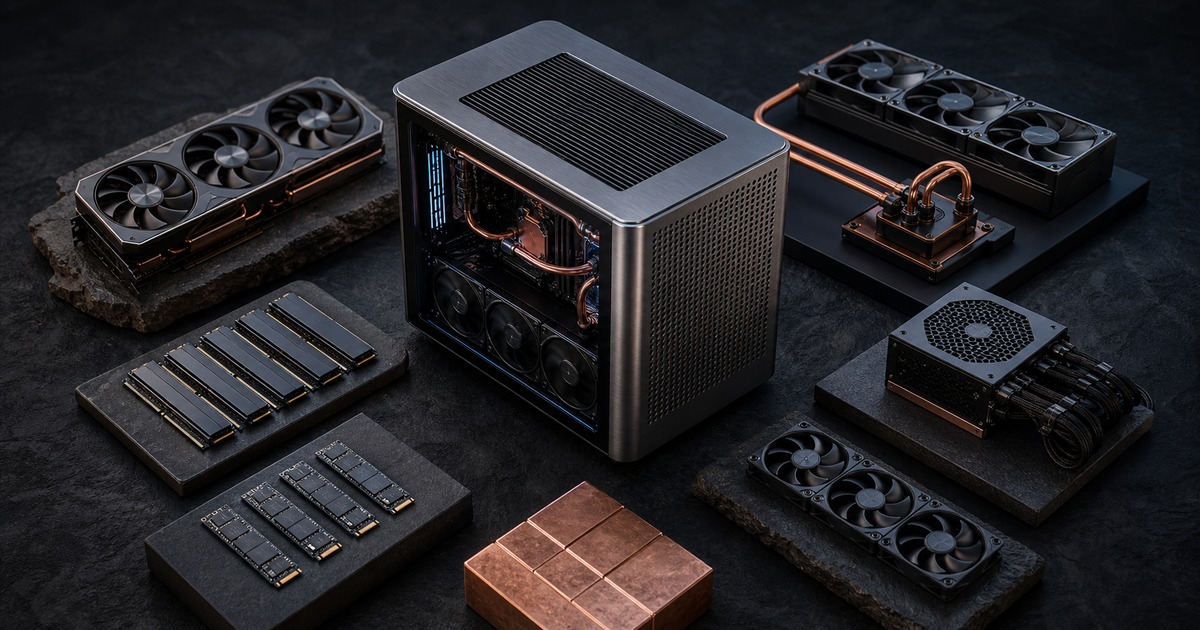
Create separate lines for accelerators, host processor, system memory, storage, network interfaces, power supply, cooling, chassis, rack or workspace needs, and installation. Add serving software integration, observability, backups, patching, and security review. Free software still consumes engineering and operational capacity.
Model fit deserves its own test. Quantization can reduce memory demand, but it may change task behavior and performance. Multiple devices can expand capacity, but they also introduce communication overhead and additional failure paths. Treat the exact model file, precision, inference engine, and hardware topology as one benchmarked configuration.
The analysis of local AI ownership economics is a useful prompt for recurring-cost categories. It cannot supply your electricity, staffing, utilization, or replacement assumptions. State the planning period and show which cost changes with use and which remains even when the system is idle.
Add resilience according to the business consequence, not habit. A research sandbox may tolerate manual recovery. A workflow used throughout the day may need spare capacity, replacement parts, tested backups, or a fallback service. Record the recovery target and prove the selected design can meet it before assigning a reliability label.
Buy capacity in evidence-backed stages
Separate a learning rig, a pilot system, and production capacity. The learning stage validates model fit and team capability. The pilot measures real demand and correction work. Only then should the team size sustained capacity. This sequence reduces the chance of buying for imagined volume or an untested model.
Preserve upgrade paths where the premium is justified: available power headroom, accessible memory slots, storage bays, suitable network capacity, and a chassis that can be maintained. Avoid paying for flexibility that has no plausible workload trigger. Every reserve should link to a stated uncertainty.
Training is another budget line. Open university AI courses may support foundational learning, while hands-on serving, monitoring, and recovery still require practical exercises on the selected stack. Course enrollment cannot replace an operating test.
Frequently Asked Questions
It depends on the tested workload and existing environment. Compute may be prominent, but power, cooling, storage, integration, operations, and resilience can materially change the total.
Benchmark representative work on comparable capacity or form a provisional range from official documentation, then require direct testing before final procurement.
Only when a stated demand or recovery uncertainty justifies it. Link every reserve to concurrency, growth, maintenance, failure recovery, or an upgrade trigger.
It can reduce memory demand, but the exact quantized artifact must be retested because task quality, speed, compatibility, and operating behavior may change.
For a workload benchmark and staged infrastructure plan, AI4SALE private AI deployment can define the evidence needed before procurement. The resulting recommendation remains conditional on tested models, current quotes, the site environment, and accountable operations.