AI evals for business workflows should answer a business question: can this configured system complete an eligible task within an agreed boundary, while making errors visible and recoverable? A leaderboard score cannot answer that. It does not include your source data, permissions, tools, handoffs, prohibited actions, or the cost of a wrong result.
Begin with one workflow and one decision. Name the trigger, user, allowed inputs, expected destination, human authority, and consequences of failure. Then write the eval before tuning the model. If the team chooses cases and thresholds after seeing output, the test becomes a demonstration rather than a decision instrument.
Write the evaluation contract around the task
Define success as an observable end state. A support triage agent may need to route an eligible ticket, attach the cited policy, preserve the original message, and escalate uncertainty. Fluency is not the outcome. The test must inspect the record delivered to the next person or system.
Separate critical requirements from preferences. A fabricated source or unauthorized action can be an automatic failure. Tone, formatting, and small efficiency differences may be scored without hiding a safety breach. This prevents a high average from compensating for one unacceptable category.
The founder trust checklist for confident AI failures offers prompts for inspecting evidence and authority. It does not certify another workflow. Use it to formulate questions, then test the actual configured process.
Build a dataset that represents operating reality
Collect ordinary cases, boundary cases, rare high-consequence cases, missing information, conflicting sources, malicious instructions, tool outages, and requests that must be refused. Label why each case belongs. A random sample of historical traffic may omit the failures that matter most.
Keep development and decision sets separate. The team can use one set to improve prompts and routing, but acceptance should run on held-out material whose expected result was defined independently. Version the cases, source documents, policy, model, prompts, tools, and grader so a later run remains comparable.
Use deterministic checks where possible: schema validity, permitted destination, citation presence, tool arguments, record completeness, and forbidden data exposure. Use human review for judgment that cannot be reduced honestly. Record disagreement instead of forcing every ambiguous case into a false gold label.
A metric is trustworthy only when its denominator and scope are explicit. The article on three checks for invented agent metrics is relevant here, but the acceptance rule still belongs to the owner of this workflow.
Turn results into a release decision
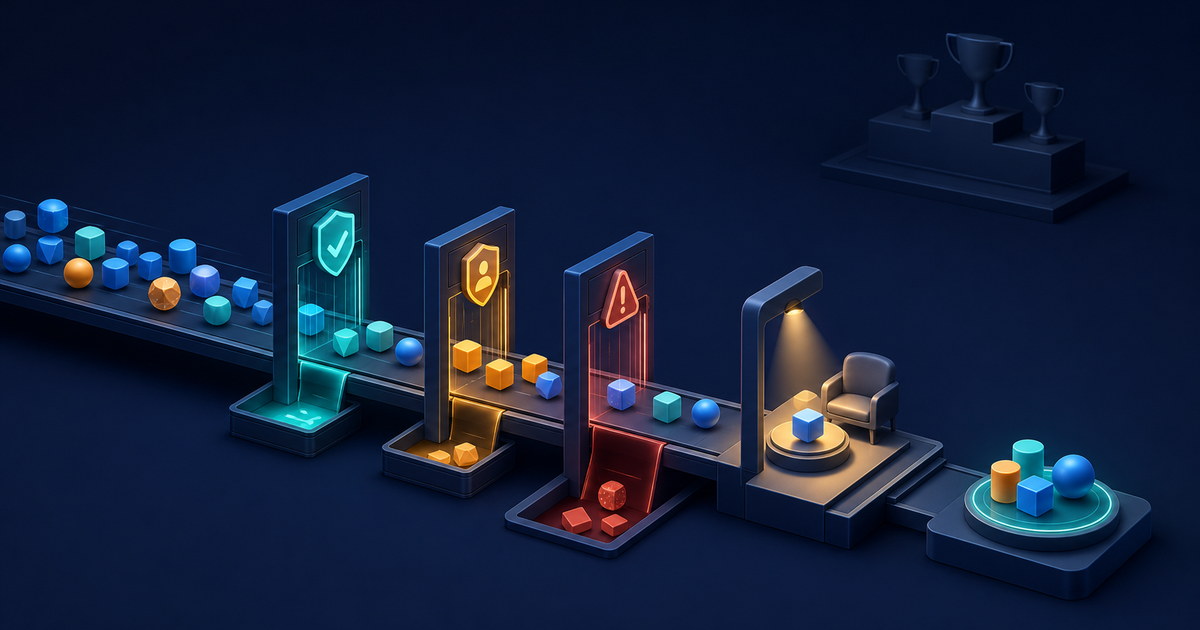
Report results by failure class and consequence, not only as one accuracy number. Show critical misses, unsupported claims, prohibited actions, recovery success, reviewer effort, latency, and cost. Include the count of eligible cases and any missing or excluded data.
Set a stop rule before the run. One unauthorized external action may block release even when hundreds of routine cases pass. A low-risk wording issue may enter a repair queue. The decision table should say which failures require rejection, correction, a narrower scope, or another controlled test.
Have someone outside the implementation path reproduce a sample and challenge the labels. Independent review should verify inputs, configuration, calculations, exceptions, and claimed completion. The documented verified-completion release illustrates a receipt-oriented approach in its own product context; it is not proof that a client workflow has passed evaluation.
After release, sample live cases and route new failures back into the taxonomy. Production drift, policy changes, new tools, and user behavior can invalidate an earlier result. An eval suite is maintained evidence, not a certificate that survives every change.
Frequently Asked Questions
Measure the final task outcome, evidence support, unsafe behavior, correction effort, handoff quality, cost, and recoverability for eligible cases.
A benchmark compares capability on a standardized task; a workflow eval tests a configured system inside a specific operating process and decision boundary.
The workflow owner, risk owner, operator, and independent reviewer should agree on criteria before results are examined.
It should fail when a prohibited action, unsupported claim, critical miss, unrecoverable handoff, or breached cost boundary occurs.
To define a workflow-specific dataset, failure policy, reviewer role, and release threshold, use AI governance and agent audit. The outcome is a bounded decision record, not a guarantee of perfect safety or universal production suitability.