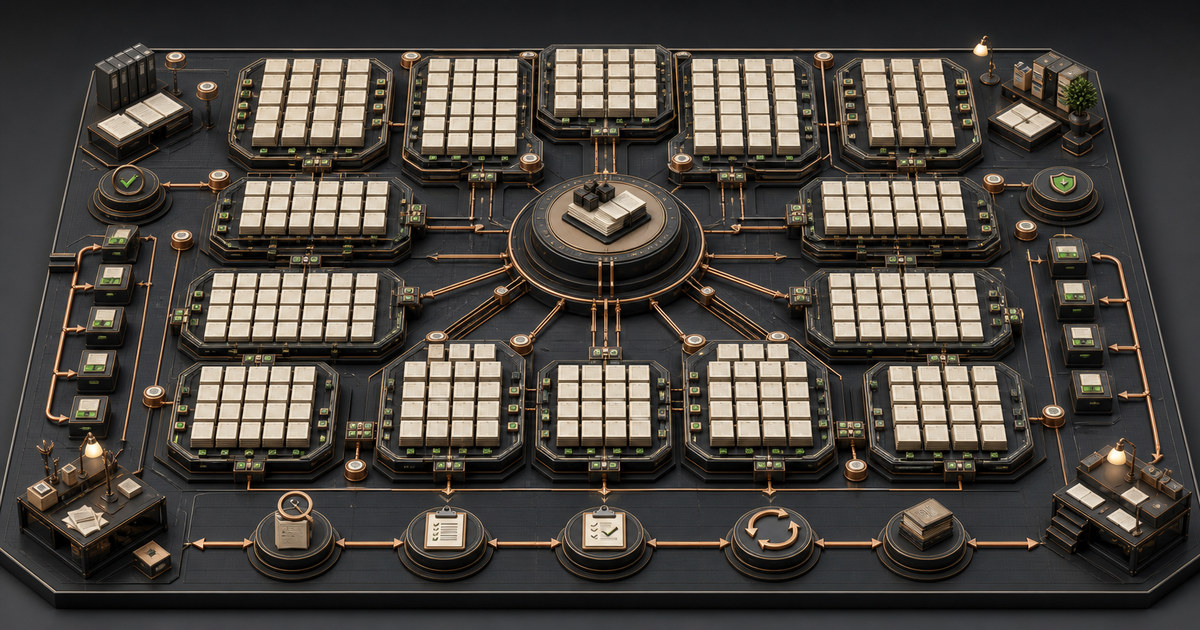
To build a 150-article knowledge engine, treat the collection as an operating system rather than a writing target. Every article needs a unique search job, an evidence boundary, a place in the topic graph, an accountable owner, and a path to maintenance. Production volume is useful only when the pages remain distinct, connected, accurate, and able to support real reader decisions.
Design the knowledge map before opening the queue
Start with business domains and the questions people ask inside them. Group those questions by intent: learn, compare, implement, evaluate, or act. Then assign one canonical page to each primary query. A topic identifier, audience, funnel stage, proof pack, support links, and target page should be decided before drafting begins.
Check the map for collisions. Similar titles can represent different decisions, while different wording can conceal the same search job. The editor needs a merge rule and authority to stop a weak row. The staged go-to-market playbook provides a useful planning principle: sequence work by evidence and readiness instead of releasing the entire inventory at once.
The map should also show source ownership. Separate authoritative evidence, internal operating context, examples, and hypotheses. A page may explain a method without claiming a measured outcome. If a commercial result is cited, attach it to the named case, period, and system that produced the record.
Estimate editorial capacity before assigning dates. Research-heavy and high-risk pages need more review than stable explanatory topics. A realistic queue protects quality better than a calendar that assumes every row requires identical effort.
Run small production cells with hard handoffs
Build the engine in bounded batches. Each row moves through source review, brief, draft, subject check, SEO check, originality scan, link verification, image preparation, artifact synchronization, and release review. A machine can enforce file shape and repeated-language rules, but a qualified reviewer approves meaning.
- Lock the canonical title, query, intent, and funnel stage.
- Verify every evidence URL before writing public claims.
- Keep external sources in private provenance metadata.
- Place contextual internal links inside useful explanations.
- Reject unsupported numbers and universal outcome promises.
- Synchronize the article, body, prompt, image, and review receipt.
- Release only after the destination and rollback path are ready.
People remain part of the machine. Editors need search judgment, subject owners need proof judgment, and operators need enough technical literacy to inspect failures. The practical route to AI upskilling is relevant because a content engine becomes fragile when only one person understands its prompts, validation, or evidence rules.
Cost appears in research, editing, image work, maintenance, tooling, and coordination. Use the payback lens for technology investment to decide which controls deserve automation and which require human review. Do not claim savings until the team measures the old and new process under comparable conditions.
Operate the graph after the last draft
A knowledge engine begins producing operational value after publication, when teams can find, cite, update, and reuse its pages. Maintain a registry of owners, source dates, link status, queries, changes, and downstream use. Schedule review by risk and volatility rather than assigning every article the same calendar.
Measure the system in layers. Indexation and visibility describe discoverability. Useful visits and reader actions describe engagement. Assisted sales conversations show commercial relevance. Accepted opportunities and revenue require CRM evidence. Internal reuse may matter even when a page has modest public traffic. No single dashboard number should replace these distinctions.
Frequently Asked Questions
Because the useful system includes canonical topics, evidence, links, owners, release controls, refresh work, and reuse, not only published pages.
No. Small batches expose semantic, evidence, linking, and operational problems before they spread through the whole programme.
File validation, URL checks, duplicate scans, metadata checks, queue state, and change alerts are good candidates. Meaning and proof still need accountable review.
Track discoverability, useful engagement, assisted conversations, accepted opportunities, revenue, and internal reuse as separate layers with their own evidence.
When evidence changes, identify every affected page from the lineage graph. When two articles converge, merge or narrow them. When a target page disappears, stop release until the path is repaired. Agencies that want a governed content engine connected to research, client approval, and delivery can review AI systems for marketing agencies.