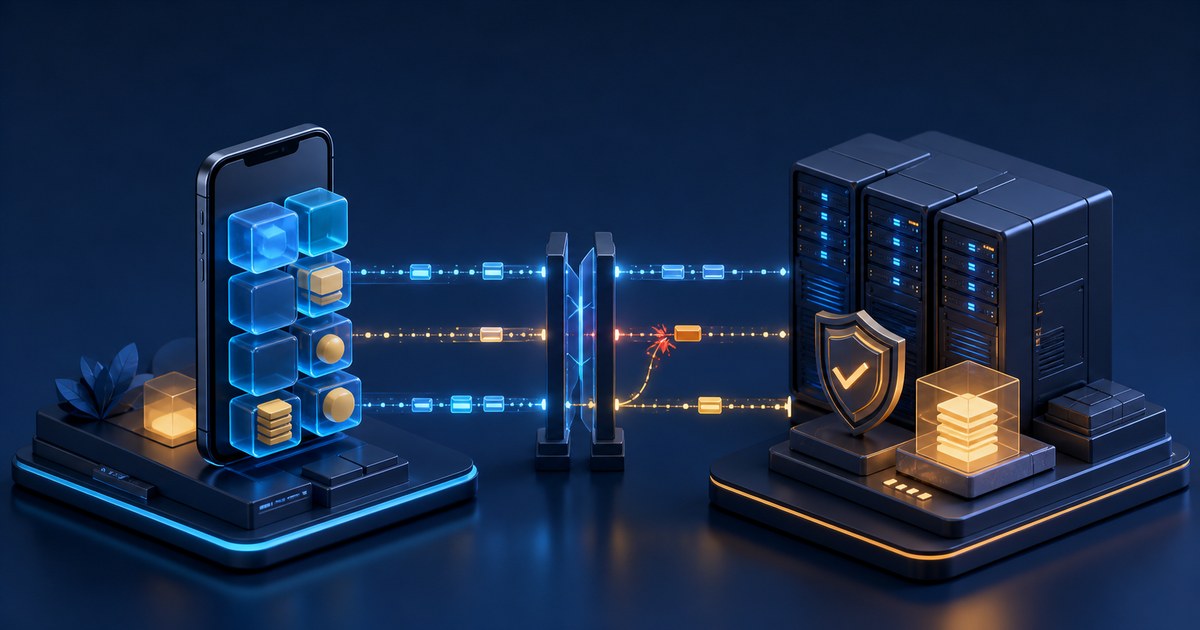
Product reliability is shaped long before an uptime chart turns red. A client can lose connectivity after a user taps submit, receive an old response after a newer one, or repeat a request because the first acknowledgement never arrived. The server may be healthy while the person sees a stale screen or an uncertain payment. Architecture becomes useful when it defines the correct outcome for each of those moments.
Do not decide placement by asking whether logic feels like frontend or backend work. Compare the consequence of disagreement. The component that can verify current permissions, durable state, contractual rules, and irreversible effects should make the authoritative decision. The client can collect input, preview a change, and keep the journey responsive, but it should not invent acceptance.
Choose placement by failure consequence
List the product actions that matter: save a draft, approve a request, change access, place an order, publish an asset, or trigger an external system. For each action, record who owns the source of truth, whether offline work is allowed, what can be reversed, and what evidence an operator needs after a dispute.
Some validation belongs in both places for different reasons. A client can flag a missing field immediately. The service still checks the request against current policy, account state, and supported application version. Duplicated validation is not wasted when one layer improves interaction and the other protects authority.
Give every consequential write a stable operation identifier. If the response times out, the client can ask for the status of that operation instead of blindly creating another one. Idempotent handling prevents a retry from duplicating an order or approval. The article about selling payback periods rather than feature lists is relevant because recovery work should protect a valuable journey, not architecture for its own sake.
Write a synchronization contract
State which data may be cached, how freshness is shown, and when local work becomes provisional. A draft might be editable without a network. A permission change usually cannot wait for later reconciliation. If the product supports queued writes, define expiry, ordering, conflict resolution, and the message shown when the server rejects a local assumption.
Optimistic interfaces need an honest visual state. The user should know whether a change is pending, accepted, or needs attention. Silent rollback turns a technical decision into lost trust. Silent overwrite is worse when two people or devices edit the same record. Decide whether the product merges fields, chooses a version, or asks a person to resolve the conflict.
Retries must have limits and ownership. A client retry, gateway retry, worker retry, and provider retry can multiply one action into a surge. Set timeouts, backoff, attempt ceilings, and a terminal state that support can diagnose. Three questions before buying AI offers a useful ownership test for any dependency, although it does not prescribe this architecture.
Trace the boundary without collecting unnecessary content. Request identifiers, state transitions, validation outcomes, dependency errors, and client version usually explain more than a raw payload dump. Logs should let the team reconstruct the journey while respecting access and retention rules.
Test recovery as a user journey
Failure testing should begin with a task, not a server. Submit an action and cut the network before the response. Open an old client after a schema change. Revoke permission while a form remains open. Send two edits from different devices. For every scenario, define the durable record, the screen state, the permitted retry, and the operator evidence.
Measure the interruption that users experience. Useful signals include accepted action rate, duplicate prevention, conflict frequency, recovery completion, stale-state exposure, and time until the person can continue the task. Infrastructure availability is only one input. A green service can still strand users behind inconsistent state.
Release plans also need compatibility rules. The service should know which clients it supports and return a deliberate upgrade path for versions it cannot safely interpret. Cached data and queued commands need migration tests. Feature flags must not give client and server different meanings for the same status.
Portal failures show what happens when workflow ownership is spread across pages and teams. The analysis of company portals built around management views helps expose that organizational risk without proving a technical result for another product.
Frequently Asked Questions
Keep final authority for current permissions, durable business state, contractual rules, and irreversible effects on a controlled service.
Yes, when the team defines which reads and writes are allowed, how freshness is shown, and how queued work or conflicts are resolved.
They let a client safely check or repeat a timed-out action without creating a duplicate order, approval, or other side effect.
Measure the durable outcome, the state visible to the user, recovery completion, conflict handling, and the evidence available to operators.
If your team has named the critical journeys, state owners, and failure scenarios, AI4SALE AI product development can structure those inputs into an architecture decision and a testable delivery scope. This is a product-design engagement, not a promise of uptime or adoption.