A tool-using agent can fail in ways that an ordinary application threat model misses. Untrusted content can influence a decision. A correct tool call can reach the wrong account. A human approval can be attached to a request that changed after review. An agent can also repeat a valid action until the business consequence is no longer acceptable.
AI4SALE performs release-specific threat modeling for one agent and its connected business systems. We map authority, identify abuse and failure paths, rank them against the buyer’s operating consequences, implement the highest-priority safeguards, and run adversarial acceptance tests. The engagement returns evidence for a scoped release decision, not a claim that the agent is permanently secure.
The useful unit is an end-to-end action path
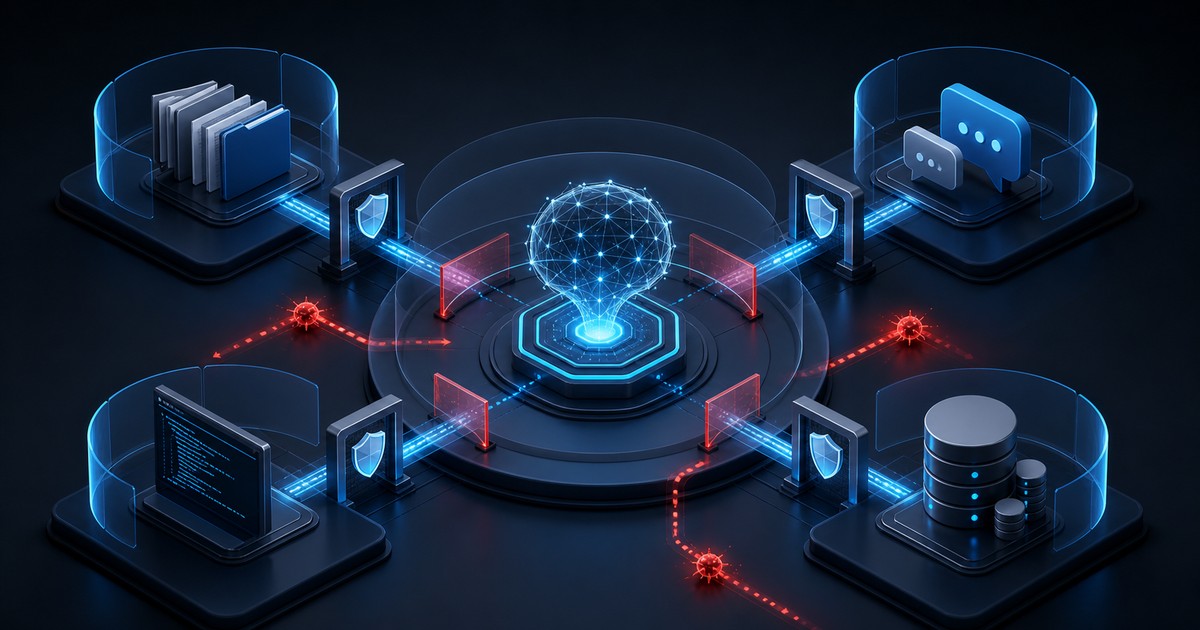
A diagram of models and databases is not enough. The model must show how a user or external source can influence a decision that becomes a real read, write, send, payment, permission, deletion, or publication. We follow that path through identity, retrieval, prompt context, policy, tool arguments, approvals, target-system state, logs, retries, and recovery.
Our engagement produces four connected artifacts:
- Authority map. It shows actors, trust boundaries, credentials, tool capabilities, destinations, data classes, and the external states the agent can change.
- Abuse-path register. It describes prerequisite, attacker or failure source, manipulated decision, reachable consequence, current detection, and control gap.
- Control changes. Priority paths are reduced through constrained operations, trusted identity, argument validation, approval binding, limits, isolation, or safe refusal.
- Adversarial evidence. Tests attempt the modeled paths and verify both the application response and the affected target system.
The first review can begin with architecture, tool definitions, redacted traces, policy files, and demonstrations in a non-production environment. We do not need raw secrets in the threat-model document. Any live testing is bounded by buyer-approved targets, test accounts, safety limits, and stop authority.
Read Threat Modeling an AI Agent With Tool Access for the scheduled conceptual guide. This companion is the service path for commissioning the working model, remediation, tests, and independent verdict.
Buying questions for AI agent threat modeling
Model it before enabling a consequential tool, expanding users or data, removing a human review, changing identity or routing, or promoting the agent into an operating process. A suspected manipulation or unexplained action is also a clear trigger.
We convert priority paths into test cases, exercise manipulated inputs, identities, arguments, destinations, approvals, retries, and failures, then compare the observed application response and target-system state with the expected policy result.
Useful inputs include architecture, agent and tool definitions, identity and permission records, data sources, policy and approval rules, representative redacted traces, target-system test access, deployment revisions, incident notes, and named system owners. Live tests require an explicitly approved boundary.
A model fails when it inventories components without tracing consequences, assumes the model is the only attacker, ignores retries and downstream state, trusts caller-provided identity, lists controls without tests, or remains unchanged after tools and permissions evolve.
An internal team can lead when security, product, platform, process, and target-system owners can expose the full action path, change integrations, authorize safe adversarial tests, and independently decide release. AI4SALE helps when agent behavior and business authority cross those ownership lines.
Enter a work email to open the agent threat-modeling pack
The protected pack contains the authority map, abuse-path worksheet, control decision table, adversarial test matrix, evidence ledger, and release verdict. It is designed for a real agent release.
Tool-Using Agent Threat-Modeling Pack
Enter your work email and the Implementation guide for We Find and Close the Dangerous Paths in a Tool-Using AI Agent will open immediately below on this page. You do not need to visit your inbox.